PrismML Launches with $22.25M Seed to Build Small Reasoning AI Models That Run on PCs and Smartphones
By admin | Sep 17, 2026 | 3 min read
If you're not yet familiar with the AI lab PrismML, you probably should be. The reason isn't the amount of funding it's secured—so far, just a $22.25 million seed round—but rather the caliber of technical minds behind it and the potentially transformative technology it's building.
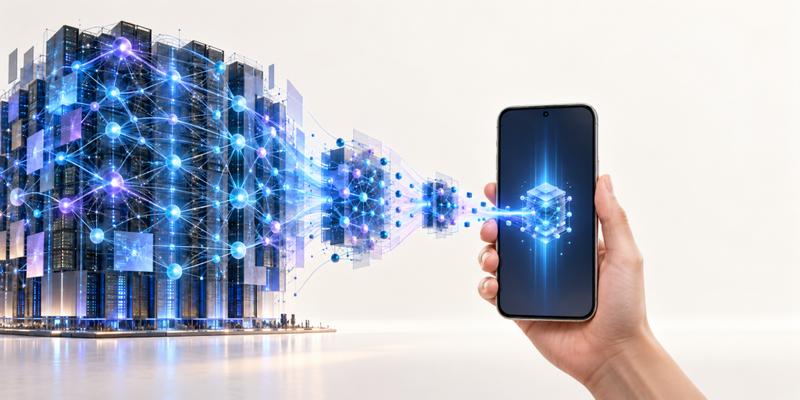
PrismML is placing a bold bet: that powerful, high-performing reasoning large language models don't actually need to be large. The company is working to shrink reasoning models down to a size that can run on personal computers and smartphones.
On Thursday, PrismML unveiled Bonsai 2 27B, the newest addition to its model family. This model compresses Qwen3.8 27B—a widely adopted open-source model from Alibaba—down to just 5.9 GB. That's compact enough to run on a PC and potentially even a high-end smartphone, representing a 9x to 10x reduction in memory compared to the original.
The startup was founded by a team of Caltech researchers and is headed by Hassibi, a Caltech professor and compression technology expert. Ion Stoica serves as an advisor to the company. Stoica co-founded Databricks (among other ventures) and directs Berkeley's renowned Sky Computing Lab, which has spawned numerous technologies and startups, including Letta and SGLang. PrismML's backers include Khosla Ventures, Cerberus Capital, and Caltech.
Of course, PrismML isn't alone in pursuing LLM compression technology. Multiverse Computing, founded by a prominent professor from Spain's Donostia International Physics Center, is another player in this space—and it has raised substantial funding.
EMBED_PLACEHOLDER_0
However, Hassibi contends that PrismML's compression approach stands apart because its models retain virtually all of the original's performance. Bonsai 2 achieves 98% of Qwen's aggregate benchmark scores—an improvement over the first Bonsai, released just a couple of months ago in March, which hit 95%. That original model has already been downloaded more than 11 million times, while PrismML's even smaller models have accumulated another 2.6 million downloads, according to the company. This demonstrates that PrismML's compression results have steadily improved across releases.
Whether the company can ever reach 100% benchmark parity remains an open question. Hassibi acknowledges that compression will likely always have some impact. Still, perfect benchmark parity is largely an academic concern. LLMs aren't so precise in their uncompressed state, and benchmarks aren't so perfectly reflective of real-world tasks, that a 2% degradation would meaningfully change how a model performs in practice. Additionally, the surrounding software—the harness a model operates within—plays a significant role in accuracy as well.
PrismML explains that it achieves these results by shrinking the "weights" that constitute a model—essentially, the information a model learns and stores during training. Typically, each weight requires 16 bits. PrismML's method, known as "ternary" weights, reduces that to just three values: +1, −1, or 0. With far smaller values to store for each weight, the model occupies dramatically less space. For a more detailed explanation of the compression technique, the project's GitHub page offers further insight.
The startup's next objective is to apply this compression technique to even larger models. As model size increases, Hassibi noted, "There is more room to be able to compress them without losing the intelligence. So I would just say, as a general trend, for larger models, it's easier to get to 100%."
Stoica told us he's enthusiastic about this technology because it enables advanced models to run directly on users' devices. "You are going to have intelligence at your fingertips, and it's going to be free because it's going to run on the device you already bought. It's also going to be private, because you're not going to send it to the cloud."
RELATED ARTICLES
Comments
Please log in to leave a comment.
No comments yet. Be the first to comment!